The Open Inference Stack
Agents break both flat-rate and per-token pricing. Cheaper tokens mean more tokens, not cheaper AI, so own the stack from metal to agents.
Contents
Use it when Deciding whether to keep sending agent workloads to a proprietary API or to self-host inference on your own infrastructure.
Agents break the pricing. Subscription pricing was designed for humans typing at human speed. Flat-rate pricing and autonomous agent workloads are structurally mismatched, and per-token billing turns every agent loop into a bigger bill.
Cheaper tokens mean more tokens, not cheaper AI. Economists call this the Jevons Paradox. As coal engines became more efficient, total coal consumption increased. Every efficiency gain unlocks new use cases that consume more than the gain saved.
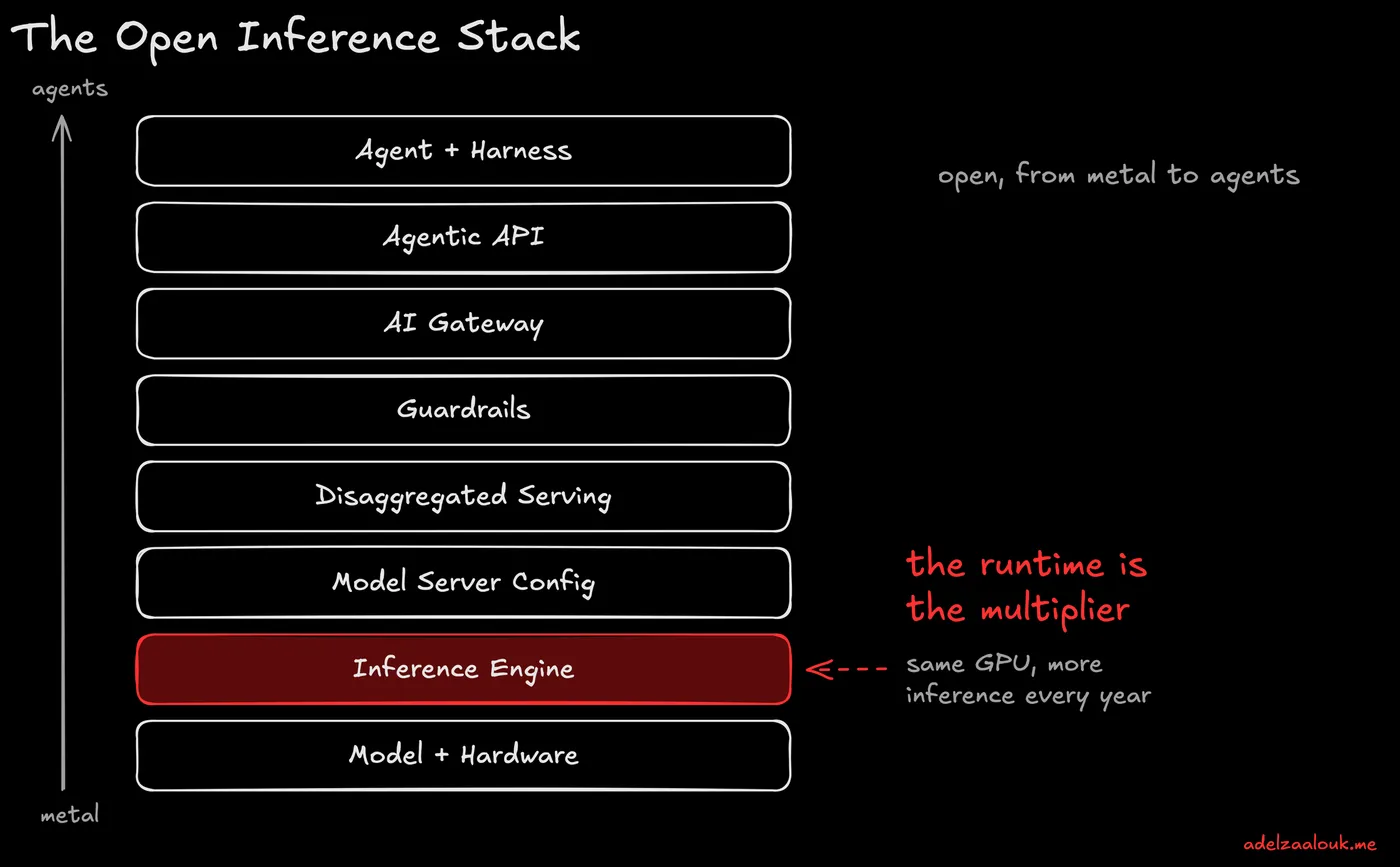
The way out is an open stack, from metal to agents. Eight layers must work together, and every layer interacts with every other layer:
- Agent and harness, inside the sandbox
- Agentic API layer
- AI gateway
- Guardrails
- Disaggregated serving
- Model server config
- Inference engine
- Model and hardware
You can’t debug failing tool calls when you can’t see the parser, and you cannot debug this stack when half of it is closed.
The runtime is a multiplier. Hardware normally depreciates. GPUs for open inference do the opposite: the chips do not change, but the software running on them keeps improving, so the same GPU produces more useful inference every year.