Red Teaming as a Discipline
LLMs are not deterministic software and the attack surface is natural language. Safety cannot be bolted on; it is built into how you develop.
Contents
Use it when Planning how to test a model or agent for jailbreaks before it reaches production, instead of hoping it won't break in the field.
LLMs are not deterministic software. Traditional software testing falls short. Models don’t just have bugs you can find and patch; they have vulnerabilities that can be exploited through carefully crafted prompts. The attack surface is natural language.
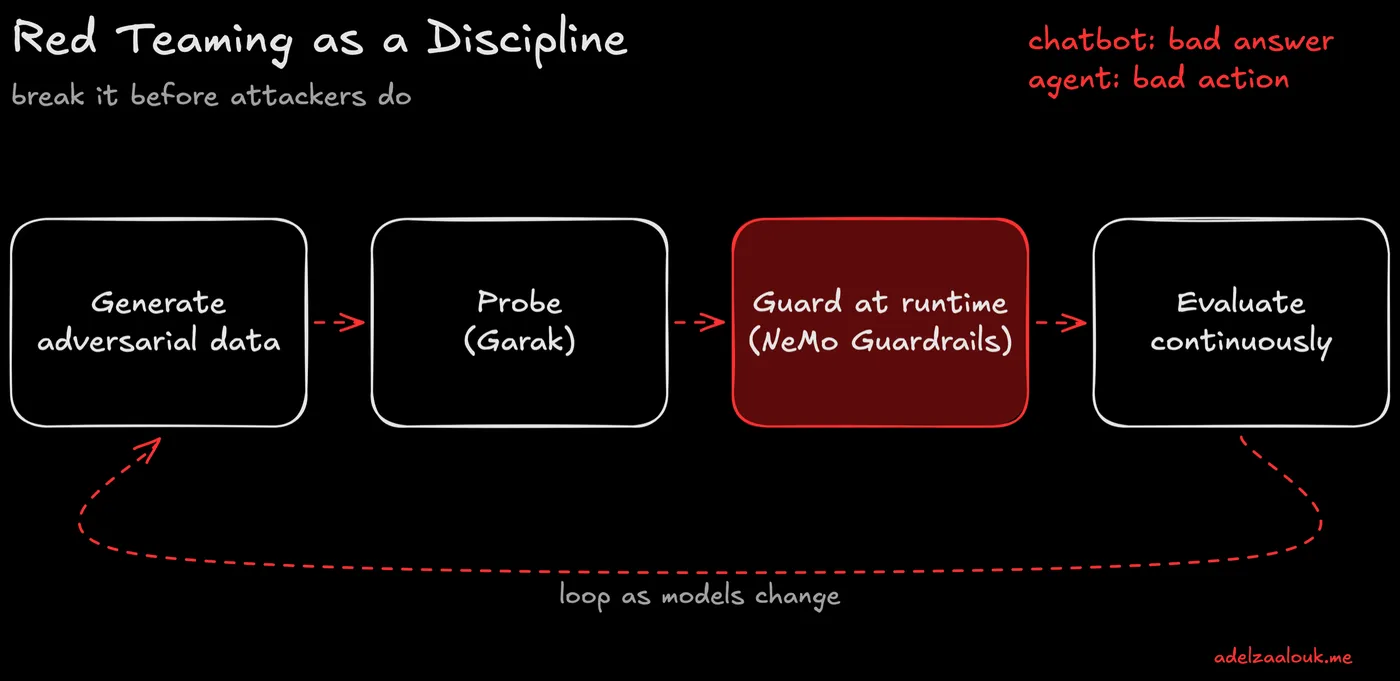
The stakes rise with agents. A chatbot vulnerability gives you a bad answer. An agent vulnerability gives you a bad action.
Red teaming is deliberately trying to break your own system before real attackers do. Most organizations either skip it or rely on ad-hoc manual efforts that don’t scale, so models reach production without safety validation.
Safety is built into how you develop, not bolted on after deployment. One pipeline, triggered with a single call:
- SDG Hub generates adversarial data across harm categories.
- Garak runs increasingly complex jailbreak attempts.
- NeMo Guardrails intercepts harmful outputs at the inference boundary.
- Eval Hub triggers the whole workflow and keeps it continuous as models evolve.
Test before deployment, protect at runtime, observe throughout the lifecycle. AI safety as code.